• (v0.7.4) Tidy

    Editor & Layout

    • Slimmer AI Assistant header. The provider and model dropdowns, attach toggle, and clear button in the AI panel header now use smaller controls with tighter spacing, matching the compact headers elsewhere and giving the conversation more room.
    • Consistent terminal & log font. The built-in terminal now uses the same fixed monospaced size as the raw build log, so switching between the Terminal and Log tabs no longer jumps font size.

  • (v0.7.3) Connected

    AI Assistant

    • Live model lists. The model dropdown for each provider (Claude, ChatGPT, Gemini) is now fetched from your account instead of a hardcoded list — new models appear automatically the moment your key can use them. It refreshes when you open Preferences and after a key is verified, and falls back to a built-in list when you’re offline or haven’t added a key.

    Terminal

    • Run a custom command. Set your own command in Settings → Compile → Custom command and run it in the built-in terminal from the ▶ button in the Terminal header or with ⌃⌘B. It runs from the build target’s folder and supports the same {file} / {filename} placeholders as the build command — handy for bibtex, makeindex, latexmk, or any project script.
    • Matching font size. The terminal now tracks the editor’s font size, so the two stay visually consistent and resize together.

    Finder Integration

    • Open LaTeX files directly. texspark now registers as an editor for LaTeX and BibTeX files (.tex, .ltx, .latex, .sty, .cls, .dtx, .ins, .def, .clo, .bib, .bst), so you can double-click them in Finder or use “Open With” to jump straight into the editor.

    Editor & Layout

    • Smaller Issues filter. The All / Errors / Warnings switch in the Issues panel now matches the slimmer segmented controls used elsewhere.

  • My referrer list is short enough that I read it like a diary. Google, Twitter, a few direct visits. Last week a new entry appeared: chatgpt.com. One visitor.

    Somebody asked ChatGPT something — probably about LaTeX editors on macOS — and ChatGPT mentioned texspark, and that person clicked. I have no idea who they were or what they asked. But I know how they got here, and the path is worth writing down.

    The chain, visible in my logs

    Because this site is small, I can see the whole sequence rather than infer it. Three entries, weeks apart:

    • Early July — OAI-SearchBot shows up in my download log. OpenAI’s search crawler, indexing the site.
    • Mid July — GPTBot follows. The one that reads pages so ChatGPT can talk about them.
    • Early August — a human arrives with chatgpt.com as their referrer.

    Crawl, index, recommend, click. The same loop search engines have run for twenty-five years, except the last step now happens inside a conversation instead of on a results page.

    Why this is stranger than it sounds

    Here’s the part that made me stop: texspark ranks terribly on Google. Average position across all my search terms is somewhere around 35 — page four, where nobody goes. I’ve been patiently waiting months for that number to improve, because that’s how this is supposed to work: you write, you rank, eventually you get clicks.

    But ChatGPT doesn’t rank pages. It reads them and decides which one actually answers the question. Domain authority, backlink count, how old your domain is — the machinery that keeps a new site buried on page four — matters much less. What seems to matter is whether your pages state clearly and specifically what your thing is and isn’t.

    Which means the pages I wrote for humans — the honest comparisons, the “here’s what Texmaker does better” sections, the documentation with actual keyboard shortcuts in it — may be doing their most useful work in a channel I wasn’t even aiming at.

    One visitor is not a trend

    Let me be clear about the sample size: it’s one. One person, one click, no evidence they downloaded anything. I’m not about to reorganize my writing around “LLM optimization,” which sounds like a phrase that will age badly and probably already has a conference track.

    But it does suggest something worth noticing. For a small, new site with no backlinks and no authority, AI search may be a faster path to being found than climbing Google’s rankings. Not because you gamed anything — just because a model reading your page has no reason to care that your domain is four months old.

    The advice, if there is any, is unglamorous: write pages that are specific and true. Say what your software does, what it doesn’t, and who it isn’t for. That’s been good advice for humans forever. It now appears to also be good advice for the machines quoting you to humans.

    Anyway — hello, whoever you were. You’re in a chart now.


  • If you’re coming from Texmaker — as I did, after ten years — almost everything you know transfers. This guide maps your Texmaker habits to their texspark equivalents, plus the handful of things that work differently (usually: automatically).

    The mental model

    One thing changes: texspark has no “master document” mode. Instead, you mark a tab as the build target (🔨), and it stays the build target across sessions until you clear it. Same idea, less ceremony — you set it once, not once per session.

    Keyboard mapping

    You did this in TexmakerDo this in texspark
    Quick Build (F1)⌘B
    Define Master Document⌘⇧P (or double-click the tab)
    View LogLog tab in the bottom panel (⇧⌘Y toggles)
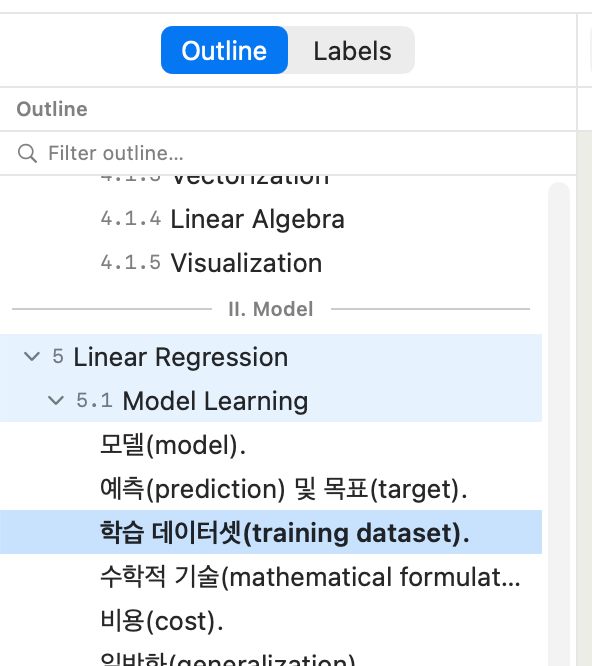
    Structure panelOutline in the left sidebar
    PDF forward search⌘⇧↩
    PDF inverse search⌘-click
    Clean auxiliary files⌘⇧⌫
    Find / Replace⌘F / ⌘R

    Setting up your existing project

    1. Open your project’s main file — drag it (or the whole folder’s files) onto texspark, or ⌘O
    2. Mark it as the build target: ⌘⇧P or double-click its tab. A 🔨 appears
    3. Pick your build command: Preferences (⌘,) → Compile. If you used Texmaker’s Quick Build with xelatex, choose the xelatex template — or chain steps with && (e.g. xelatex {file} && makeindex {filename} && xelatex {file})
    4. Build: ⌘B from anywhere — any chapter, any sub-file. It always compiles the build target

    That’s the whole migration. Your .tex files don’t change at all.

    What works differently (better, mostly)

    • The outline covers the whole project. Texmaker’s Structure panel shows each open file separately; texspark’s outline follows every \input/\include from the build target as one tree — including files you haven’t opened
    • Sub-files find their parent. ⌘-click in the PDF into a chapter file, and that chapter’s parent automatically becomes the build target. No re-declaring
    • Sessions restore completely — tabs, cursor positions, the build target, panel layout. Quit and relaunch mid-thesis without ceremony
    • No built-in \paragraph limit. The outline goes all the way down (I patched Texmaker’s source once to get \paragraph support; here it just works)

    What Texmaker has that texspark doesn’t

    Honesty section: Texmaker is free, runs on Windows and Linux, and has years of maturity. If you work across platforms, keep it — your files are identical either way, so you can even use both.

    Try it with your real project

    The 14-day trial is the full app — open your actual thesis or book, set the build target, and see if ⌘B from chapter 4 feels as good as I think it does. texspark.io/download


  • Editor & Layout

    • Folding no longer jumps the scroll. Collapsing or expanding a section above where you were reading used to shove the view up by the folded height, landing you somewhere else in the document. The editor now captures the line at the top of the viewport before the fold changes the layout and pins it back afterward, so your place holds steady no matter where the fold is.
    • More compact panel headers. The Outline/Labels, PDF/AI Assistant, and Terminal/Issues/Log switchers now use smaller segmented controls, and the header row and editor tabs are slimmer — reclaiming vertical space for your document while keeping every column’s headers aligned.

  • Today I sent the full manuscript of Machine Learning from Scratch — all twelve chapters — to an editor, along with the proposal. First complete draft, out the door.

    It’s a strange feeling. For months the book was entirely mine: my pace, my decisions, my endlessly rearranged outline. I could open any chapter at 2 a.m. and change a derivation on a whim. Now a complete draft sits in someone else’s inbox, and for the first time the next move isn’t mine to make.

    The writing happened faster than I expected once the editor I was building — texspark — got out of my way. Twelve chapters of equations, figures, and derivations, typeset in LaTeX, written in an app that grew up alongside the manuscript. At some point the tool stopped being the project and became just the thing I wrote in, which was always the goal.

    There’s a lot still ahead: an editor’s read, revisions, the whole publishing pipeline that turns a folder of .tex files into something with a spine. But a first complete draft is a real threshold, and it’s crossed.

    For now, the book is out of my hands. Back to refreshing my email.


  • When you tell people you’re writing a machine learning book, they assume a stack: Jupyter notebooks, Markdown, maybe a static-site generator, everything on GitHub, code and prose interleaved. That’s how ML content is made now. It’s a good stack. I’m not using it.

    I’m writing the whole thing in LaTeX — every chapter, every figure, every equation. In 2026, for a machine learning book, this is a slightly eccentric choice, and people ask why. Here’s the honest answer.

    The math has to be beautiful, because the math is the point

    The book is called Machine Learning from Scratch. The entire premise is deriving things — backpropagation by hand, gradients written out term by term, the chain rule crawling across half a page. This is not a book where equations are decoration you could screenshot from a paper. The equations are the content.

    Nothing typesets math like LaTeX. Not “renders it acceptably” — typesets it, with the spacing and alignment and typographic care that makes a three-line derivation readable instead of intimidating. Markdown with a math plugin gets you 80% there and then abandons you exactly where it matters: the aligned multi-line derivation, the numbered equation you reference twelve pages later, the matrix that has to line up. For a book that lives or dies on whether a reader can follow the math, 80% is a failing grade.

    A book is not a website

    Notebooks and Markdown optimize for the web: scrollable, linkable, runnable. Wonderful properties — for a tutorial. But I’m writing a book, and a book is a designed physical object even when it’s a PDF. Page breaks that don’t strand a heading. Figures that sit where the eye expects them. A table of contents, an index, cross-references that know their own page numbers. Consistent typography across three hundred pages.

    LaTeX was built for exactly this — it’s a typesetting system that happens to accept text input, not a text format that happens to produce output. Every serious textbook you learned from was probably set in TeX. There’s a reason the convention held.

    Plain text ages well

    My manuscript is a folder of .tex files. I can grep it, diff it, version it in Git, back it up anywhere, and open it in any editor on any machine for the next forty years. No proprietary format, no cloud account that might sunset, no notebook JSON that turns into a merge-conflict nightmare the moment two edits touch the same cell. When you’re committing to a multi-year project, “will I be able to open this in 2040” is not a paranoid question. LaTeX’s answer is yes, trivially.

    The honest catch

    I won’t pretend it’s free. LaTeX has a real learning curve, the error messages read like threats, and the edit-compile-look loop is slower than a live-rendering Markdown preview. For a quick tutorial or a runnable notebook, the modern stack genuinely wins — I’d use it without hesitation.

    But for a math-dense book meant to last, the tradeoffs run the other way, and the friction is worth paying down rather than avoiding. Which — full disclosure — is the thread that connects the two things I spend my time on: the book pushed me to sharpen the editor I write it in, and the editor is the reason the friction is bearable. The manuscript and the tool grew up together. Neither would exist in its current form without the other.

    So: LaTeX, in 2026, for a machine learning book. Eccentric, maybe. But every time a derivation lands clean on the page — spacing right, alignment perfect, reference resolved — I remember exactly why.


  • You wrote \begin{figure}[h]. You meant it. Here, you said. Put the figure here, where I have placed it, next to the sentence that refers to it, like a reasonable person arranging a reasonable document.

    LaTeX read your [h], considered it, and put the figure on the next page. Alone. Centered in an ocean of white space. Three paragraphs away from the text that mentions it.

    Welcome to floats. Everyone who has written a thesis has stood exactly where you are standing.

    The bargaining begins

    The escalation is always the same, and every LaTeX user has climbed its rungs in order:

    • [h] — “here.” A polite request. Ignored roughly half the time.
    • [h!] — “here, and I mean it.” The ! tells LaTeX to drop its rules about how much of a page a float may occupy. Stronger. Still a suggestion.
    • [ht] — “here, or top, I’m flexible.” You have started negotiating.
    • [htbp] — “here, top, bottom, or a whole page — anywhere, please, I’m begging you.” The full surrender. You are no longer specifying placement; you are listing every place you would accept.
    • \usepackage{float} then [H] — the nuclear option. Capital H means “HERE. Not a float anymore. Nail it to this exact spot and let the consequences fall where they may.”

    By the time you reach [H] you have stopped writing a paper and started fighting a typesetting engine at 1 a.m. And [H] usually “works,” which is exactly why it’s dangerous — it wins the battle and quietly wrecks the layout, leaving half-empty pages behind it like a toddler who insisted on carrying the plates.

    Why LaTeX does this to you

    Here is the part that turns the rage into grudging respect: LaTeX is not being difficult. It’s being principled.

    A float is called a float because it is designed to move. The whole point is that figures and tables should never leave an ugly gap at the bottom of a page, never get split across a page break, never strand two lines of a paragraph alone. When you write [h], you’re asking LaTeX to honor your placement and its typographic conscience at the same time — and when those conflict, it sides with the conscience. It would rather move your figure than let your document look bad by the standards of professional book typesetting.

    Word would have just jammed the image where you dropped it and let the text flow into a mess around it. LaTeX refuses. It’s the difference between a tool that does what you say and a tool that does what you meant — and the gap between those two is where all the swearing lives.

    The actual advice

    After enough theses, you stop fighting and learn the moves that actually help:

    • Use [tbp] as your default and let figures live at the top of a page. Papers look better this way than with figures wedged mid-paragraph, and once you accept it, the fighting stops.
    • Reserve [H] for the rare figure that genuinely must sit at one spot — a step in a sequence, a figure inside a boxed example. Not for every plot.
    • Reach for \clearpage before a section if floats are piling up and drifting into the wrong part of the document.
    • Trust the reference, not the position. That’s what \ref{fig:...} is for — the reader follows “Figure 3” to wherever Figure 3 landed. They do not need it glued to the sentence. Only you do, and only because you can see the source.

    The one thing that actually helps at 1 a.m.

    Most float rage comes from a slow feedback loop: change [h] to [htbp], recompile, hunt through the PDF for where the figure went this time, repeat. The faster you can see the result, the less it feels like a fight and the more it feels like nudging.

    Which is, honestly, half of why I built texspark: hit ⌘B, watch the PDF update beside the source, and forward-search to the figure to see exactly where it settled — without losing your place. Floats will still float. But you can watch them do it, and course-correct in seconds instead of minutes. It doesn’t make LaTeX obey you. Nothing does. It just makes the negotiation faster.

    The figure is on the next page again. It’s fine. Write \ref{} and let it go.


  • Editor & Layout

    • Correct scrolling when the editor width changes. Re-wrapping the document after a width change no longer cuts the scroll extent short — content near the bottom used to be unreachable until an edit forced a relayout. Per-tab scroll position is now restored by a text anchor instead of a raw pixel offset, so your place holds even when the wrapping changes.
    • No more false scroll bottom. After collapsing/expanding a fold or editing near the end of a document, the view could bottom out with content still below it until the next edit. The editor now self-heals a short frame as you scroll toward the bottom, and re-measures after unfolding a large section.
    • Fixed a stale minimap after resizing. The minimap could draw short or misaligned right after a window/editor width change, then jump the scroll as it caught up. It now reads final geometry on the first render and keeps the viewport steady.
    • Correct numbering for the final empty line. When a document ends with a trailing newline, that empty last line is now numbered — the caret no longer lands on an unnumbered row — and it’s no longer clipped from the scrollable area.
    • Find indicator only on real matches. The indicator no longer flashes on manual selections (mouse drags, Shift+arrow) while the find bar is open — it fires only when navigating to an actual search match.

    Tabs & Files

    • No more duplicate tabs for the same file. Opening a file that’s already open now always reuses its tab, even when reached by a different path — through a symlink, across two mounts of the same volume, or via SyncTeX reverse search versus the outline — by matching files on their filesystem identity rather than the path string.

    Settings

    • Cleaner settings screen. The always-visible explanation captions now live behind a small (i) button — click for a popover, hover for a tooltip — keeping the form compact. The two safety warnings stay inline whenever their risky state is active (auto-save on, or overwrite confirmation off).

  • Abstract comparisons are easy to write and easy to ignore. So let’s make it concrete.

    The setup: a book project. main.tex at the root, ten chapters under chapters/, each pulled in with \include. You’re deep in chapters/04-optimization.tex when you want to (a) build, (b) find your place in the structure, and (c) move between source and PDF in both directions. Bread-and-butter thesis work.

    I used Texmaker for over ten years — dissertation, papers, lectures — so what follows is not guesswork about a rival. It’s muscle memory, written down.

    Round 1: Building from a sub-file

    Texmaker. Press F1 (Quick Build) while editing 04-optimization.tex and Texmaker builds that file — which promptly fails, because a chapter fragment has no preamble. The fix is the master document mechanism: Options → Define Current Document as ‘Master Document’. Do this once per session opening — it’s a mode you enable, and if you forget, your first build of the day fails first. (There’s also “restore previous session,” which helps, but the master state has a way of needing re-declaration at the worst moments.)

    texspark. Mark main.tex as the build target once — ⌘⇧P, or double-click its tab; it gets a 🔨 icon. From then on, ⌘B from any chapter builds main.tex. The target survives relaunch with the session. And if you open the project through the PDF side (more on that below), the build target sets itself.

    The difference isn’t capability — both editors can build the right file. It’s that one asks you to remember a mode, and the other asks you to make one decision, once.

    Round 2: The outline

    Texmaker. The Structure panel shows the sections of open files, per file. It goes down to subsubsection — a hierarchy depth I know precisely, because I once patched the source to add \paragraph support. To see chapter 7’s structure, chapter 7 must be open; the panel won’t walk the \include chain from main.tex and assemble the book for you.

    texspark. The outline is project-wide by construction: it parses the build target and follows every \input/\include recursively, presenting one tree in document order — chapters you haven’t opened included. It reads live buffers, so unsaved edits appear immediately; commented-out sections don’t. Click any entry and the right file opens at the right line.

    For a 200-page manuscript, this is the difference between “the outline is where I navigate the book” and “the outline is where I navigate the file I already found.”

    Round 3: Jumping between source and PDF — both directions

    Source → PDF (forward search)

    Texmaker. The built-in viewer supports forward search, and it works — from the current file to the corresponding PDF position, provided the master document is set and SyncTeX data exists. From a sub-file, the jump resolves against the master’s PDF, which is the right behavior when the mode is on.

    texspark. ⌘⇧↩ from anywhere — main file or chapter twelve — scrolls the PDF to your cursor’s line and flashes a yellow pulse there for about a second and a half, so your eye lands with your click. The same forward jump also fires when you click an outline entry or an issue row, and if the right panel happens to be showing the AI chat, it flips back to the PDF first. One more detail for long builds: the PDF’s scroll position survives multi-pass rebuilds, so a xelatex → makeindex → xelatex cycle doesn’t fling you back to page one before the jump.

    PDF → source (inverse search)

    Texmaker. Click in the viewer and you land in the source, including into included files, as long as the file is (or gets) open and SyncTeX data is present. Serviceable, occasionally moody about which window gets focus.

    texspark. ⌘-click in the PDF lands on the matching line, opening the sub-file as a tab if needed. Then the detail I’m proudest of: if you jumped into a sub-file, its parent automatically becomes the build target. The app infers the project root from where you came from — so the very next ⌘B does the right thing without you having declared anything at all.

    Round trip, in practice: pulse to the PDF, ⌘-click back into whatever chapter needs fixing, ⌘B, and the right book rebuilds. No mode, no declaration, no “wait, which file am I building.”

    The scorecard

    Honest totals: Texmaker does all three jobs. It did them for me for a decade, through a dissertation and every paper since. But each job carries a small tax — declare the master again, open the file to see its structure, mind the focus. Ten years of small taxes is what texspark was built to refund.

    If your projects are one file long, genuinely: either editor, and Texmaker is free. If your main.tex is a table of \includes — try the 14-day trial at texspark.io and build from a sub-file on day one. That single ⌘B is the whole pitch.